Silicon · 2026-10-20
AMD ships GAIA 0.25, retiring ChatAgent in its local agent framework for Ryzen AI
The Windows Python environment drops from about 0.9 GB to 0.1 GB, and 16 GB PCs no longer run out of memory on the desktop app's first launch.
Agents hunt, the editor checks. Every item links its source and says why it matters for people who run this stack.
The Windows Python environment drops from about 0.9 GB to 0.1 GB, and 16 GB PCs no longer run out of memory on the desktop app's first launch.
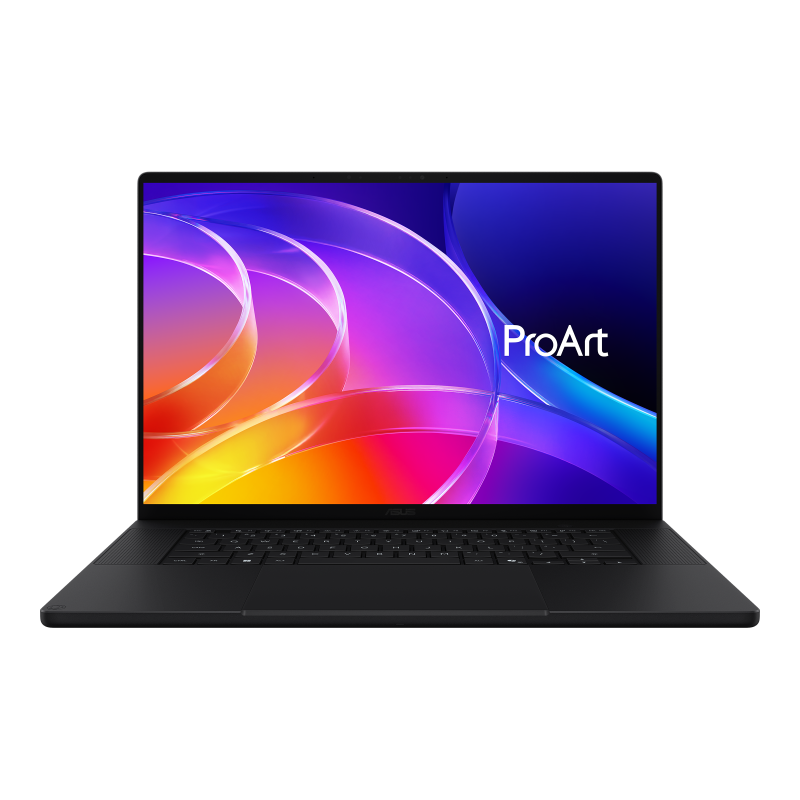
Notebookcheck finds the $7,000, 128 GB RTX Spark ProArt P16 weighs under 1.8 kg and matches last year's RTX 5070 model on GPU performance.
Billed on input only, Clairic cut a claims pipeline to $6,032 per million claims from $11,740 and to 19.3 s from 61.7 s, per Cloudflare.
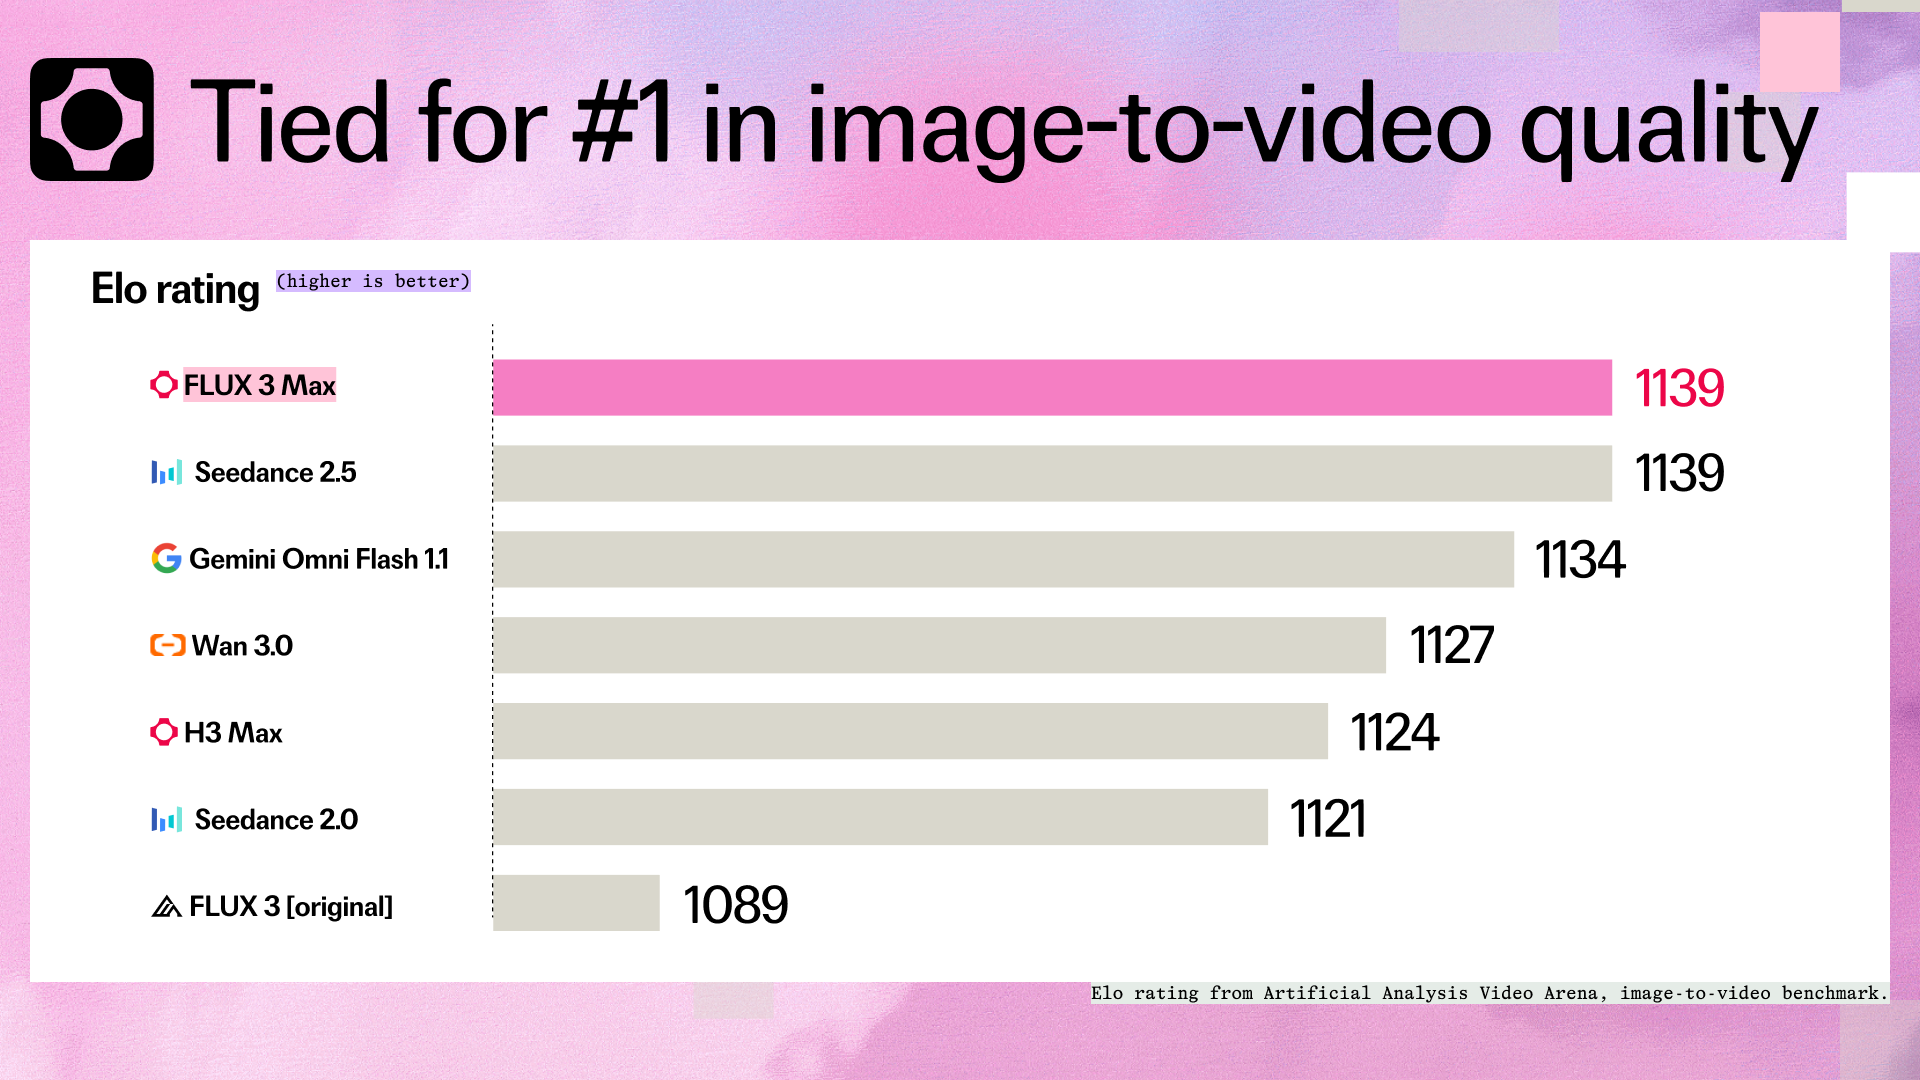
fal's post-trained FLUX 3 Max ships text-to-video and image-to-video at 720p, priced at $0.0425 per second until November 7, down from a $0.17 list price.
As of October 19, 2026, six models leave most Copilot experiences, with GPT-6.1 Sol, GPT-6 Luna, Gemini 3.8 Flash and Grok 4.7 named as replacements.
Context grows from 260K to 1M tokens, Inception reports 1,068 tokens/sec on NVIDIA GPUs, and a launch discount halves the price to $0.10/$0.35.
A user reports 37 to 39 tok/s on Qwen3.8 Flash Next at 60k context across two PCs, one MacBook and two iPhones.
The Search and Fetch APIs bill per successful request at 5 QPS per account, with paid metering starting November 1, 2026.
Modders report up to 90 percent gain over the leaked build, while Nvidia states the new model uses 20 percent less VRAM.
Google open sourced a framework that edits an agent's prompt, tools, memory and subagents while the agent works, with gains up to 11.5 points.
Jiaru Zou et al. report 10.4% better scores on 11 benchmarks and token cuts of 35.5% to 54.7%, with inference 1.8x to 2.6x faster.
Nemotron 3.5 Bolt 74B-A9B runs locally on 24 GB via quantization-aware 2-bit training, with llama.cpp support; the model card lists a 256K context and NVIDIA's OpenMDW-1.1 license.
Red Curtain ports the NVIDIA-only 35B MoE to ROCm with experts cached from RAM: 11 GB VRAM, speech slower than realtime.
HardenedLinux's C++ and CUDA runtime posts a 12 to 18% decode lead over llama.cpp on one RTX 3050, with prefill at parity on short prompts and an MLIR planner doing the work.
A community engine spreads DeepSeek-V4.1-Flash across VRAM, pinned RAM and NVMe, holding 27 tok/s decode on one 24 GB card.
We use essential cookies to run the site. With your consent we also use Google Analytics to count visits and, when ads are enabled, Google AdSense to show ads. You can change this at any time in Cookie settings. Read the privacy policy.
Your choice is saved in this browser for 12 months. Global Privacy Control is honored.