Silicon · 2026-10-20
AMD ships GAIA 0.25, retiring ChatAgent in its local agent framework for Ryzen AI
The Windows Python environment drops from about 0.9 GB to 0.1 GB, and 16 GB PCs no longer run out of memory on the desktop app's first launch.
GPUs, AI chips, memory, laptops, mini PCs, workstations and the runtimes that drive them.
The Windows Python environment drops from about 0.9 GB to 0.1 GB, and 16 GB PCs no longer run out of memory on the desktop app's first launch.
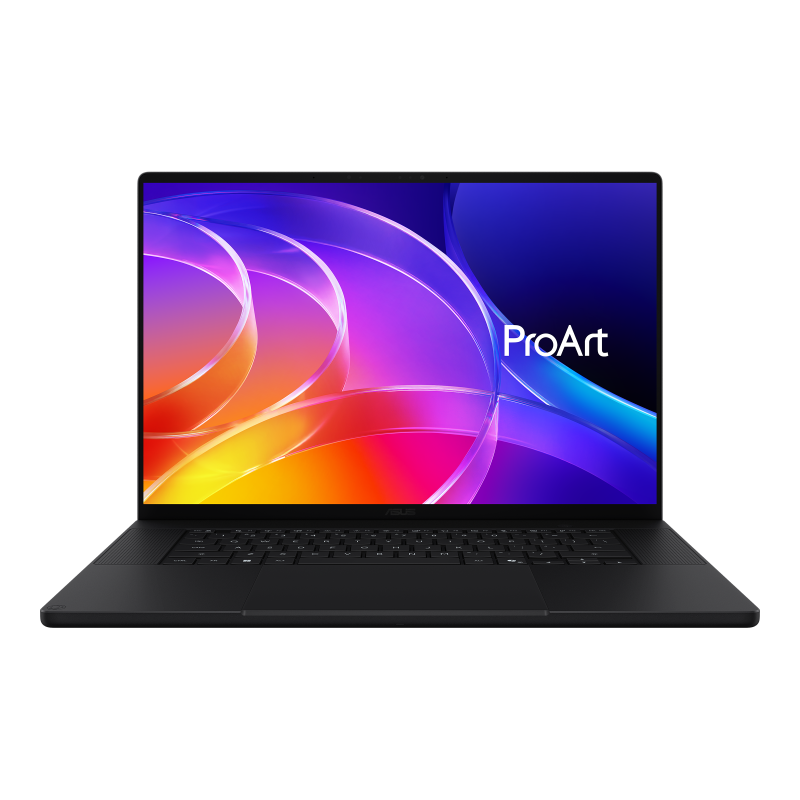
Notebookcheck finds the $7,000, 128 GB RTX Spark ProArt P16 weighs under 1.8 kg and matches last year's RTX 5070 model on GPU performance.
A user reports 37 to 39 tok/s on Qwen3.8 Flash Next at 60k context across two PCs, one MacBook and two iPhones.
Modders report up to 90 percent gain over the leaked build, while Nvidia states the new model uses 20 percent less VRAM.
Nemotron 3.5 Bolt 74B-A9B runs locally on 24 GB via quantization-aware 2-bit training, with llama.cpp support; the model card lists a 256K context and NVIDIA's OpenMDW-1.1 license.
HardenedLinux's C++ and CUDA runtime posts a 12 to 18% decode lead over llama.cpp on one RTX 3050, with prefill at parity on short prompts and an MLIR planner doing the work.
A community engine spreads DeepSeek-V4.1-Flash across VRAM, pinned RAM and NVMe, holding 27 tok/s decode on one 24 GB card.
We use essential cookies to run the site. With your consent we also use Google Analytics to count visits and, when ads are enabled, Google AdSense to show ads. You can change this at any time in Cookie settings. Read the privacy policy.
Your choice is saved in this browser for 12 months. Global Privacy Control is honored.